The question
The quant was larger than the three GPUs could hold on their own. The experiment tested explicit GPU expert splits with CPU offload and measured the decode effect under the same large-context workload.
From the original notebook
- Date: 2026-09-20 (single-day run)
- Host: 3x RTX 3090 (72 GB VRAM), 125 GB RAM, i7 CPU
- Model:
unsloth/Qwen3.8-Flash-Next-GGUFUD-Q4_K_XL — 4-part multipart GGUF, 104 GiB total (~130B MoE, 48 blocks, 512 experts/10 active, only 12 full-attention blocks) - Inference: llama.cpp flash-next fork
WORKSTATION/llama-server(build 0.3.0-dev, commit 9723942), launched viaWORKSTATION/run_qwen38_flash_next_q4km.sh - Serving: port 12705, name
flashnext-udq4kxl-200k, ctx 204800, KV q8_0 - Winner: expert blocks 12/12/12 per GPU + 12 blocks CPU + PLE on CPU → 31.1 tok/s
1. Download
aria2c hard-caps -x at 16 connections/server (165 impossible). Parallelism via 3 tmux sessions, one part each:
aria2c -x16 -s16 -k8M -c <url>. All 4 parts verified byte-exact vs HF metadata (part1 10,946,624 B … part4 12,087,983,520 B).
Model path points at part1; llama.cpp concatenates multipart GGUFs transparently.
2. The load problem: 104 GiB vs 72 GB VRAM
Obligatory CPU offload of ~25 GiB of MoE experts. Key findings:
-ncmoe N+-sm layeris a trap: layer-split ignores weight; with first-N experts on CPU, GPU0 (early, near-empty blocks) idles while GPU1/2 get overloaded contiguous buffers (repeatablefailed to allocate CUDA1 buffer of size 15788813824).-otseparator is COMMA, not semicolon — semicolons giveunknown buffer type.LOAD_MODE=noneis REQUIRED with CPU-otrules: mmap + CPU overrides double-allocate.- Historical tensor names from
run_qwen38_flash_next_q4km.sh.bak-20260905still valid:blk.N.ffn_{gate|up|down}_exps.weight,per_layer_token_embd.weight(PLE). - Explicit per-GPU expert-block ranges are the only reliable placement; everything else rides
the script’s baseline (
-ngl 999 -sm layer -ts 1,1,1 -fa on --repack --op-offload -b 16384 -ub 400 -t 14 --cpu-strict -Cr 0-13).
3. Speed A/B: expert blocks on GPU (204800 ctx, q8_0 KV, 300-token streaming bench)
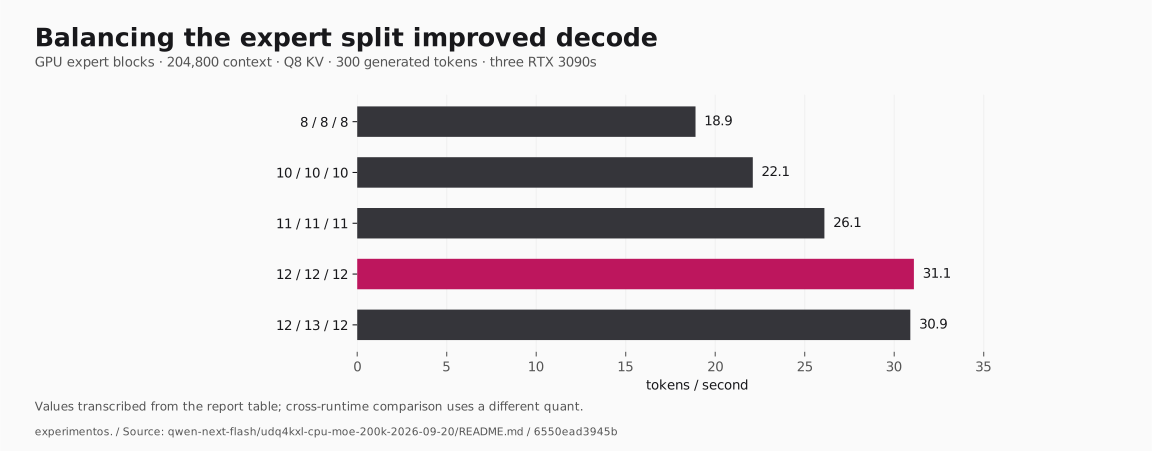
| GPU expert blocks | VRAM GiB (0/1/2) | CPU blocks | gen tok/s |
|---|---|---|---|
| 8/8/8 (24 total) | 17.3 / 16.0 / 16.6 | 24 | 18.9 |
| 10/10/10 (30) | 20.3 / 19.0 / 19.6 | 18 | 22.1 |
| 11/11/11 (33) | 21.8 / 20.5 / 21.3 | 15 | 26.1 |
| 12/12/12 (36) — winner | 23.3 / 22.0 / 22.8 | 12 | 31.1 |
| 12/13/12 (37) | 23.3 / 23.5 / 22.8 | 11 | 30.9 (plateau, tighter GPU1) |
Balanced splits beat unbalanced at equal block count (a 12/3/7 accidental split gave only 19.5 — pipeline stalls on the empty GPU dominate). 12/12/12 = same speed as 12/13/12 with better margins → production choice.
4. Verdict & context
- 31 tok/s is the physics ceiling for this quant on this host: ~25 GiB of experts must run on CPU
(
--op-offload). Reference points: old all-GPU Q4_K_M M64 did 60.5 tok/s @ 204800/q8; exl3-4bpw (all-GPU, 65.1 GB weights) did 67.6 tok/s @ 265984/q8, 66.3 @ 307200/q6. - exl3-4bpw beats UD-Q4_K_XL ~2x on speed AND reaches larger ctx, but costs 102 GB disk vs 104 GB and lacks GGUF ecosystem flexibility. This GGUF run is the llama.cpp-native deployment.
- Model fine at 204800/q8 with ~0.7 GiB margin on GPU0; higher ctx would need KV q6 or fewer GPU blocks.
5. Files
scripts/run_udq4xl.sh— winning launch wrapper (12/12/12 + PLE→CPU + LOAD_MODE=none)scripts/bench_gen.py— streaming gen tok/s benchmark- Live server: tmux/setsid, log
/tmp/udq4xl-server.log, healthcurl localhost/health
Not yet wired into qwen36_model_families.json (proxy family pending decision).
Keep exploring
Original experiment record. Workstation paths have been generalized. Detailed measurements below retain their original workload and validation boundaries.