A smaller speech model earns its place on the iPhone
Aidana transcribed the 47 matched clips 3.35 times faster, with observed English WER of 2.15% and Spanish WER of 5.37%.
I’m Vlad. I build, break, and benchmark local AI. Here are the experiments, the findings, and the lessons.
Explore the journal
Aidana transcribed the 47 matched clips 3.35 times faster, with observed English WER of 2.15% and Spanish WER of 5.37%.
Three live recovery scenarios passed, each finishing with 10/10 checks.
All three registered learning rates crossed the retention floor after eight steps and rolled back.
Sometimes the smaller model is the better fit. I compare the speed, memory, and quality before deciding what stays on the machine.
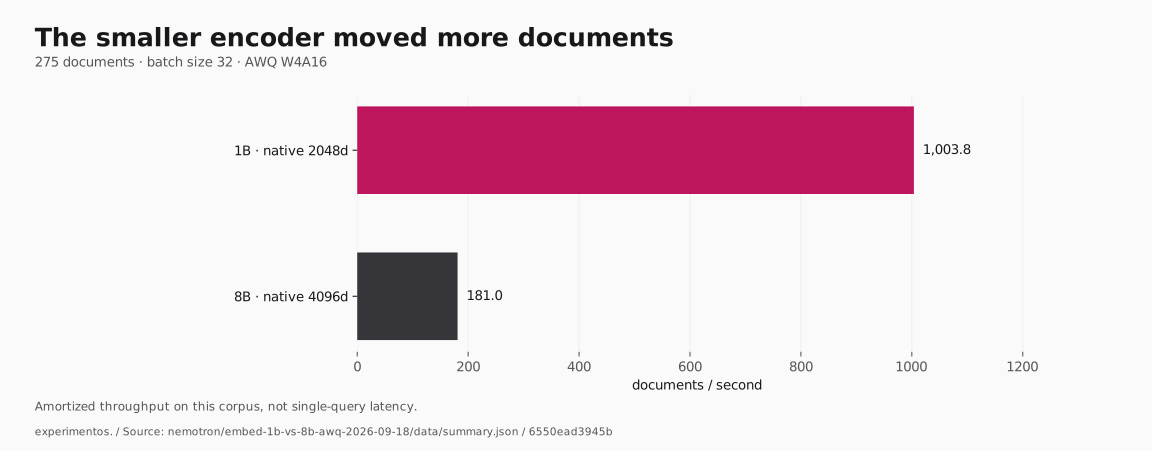
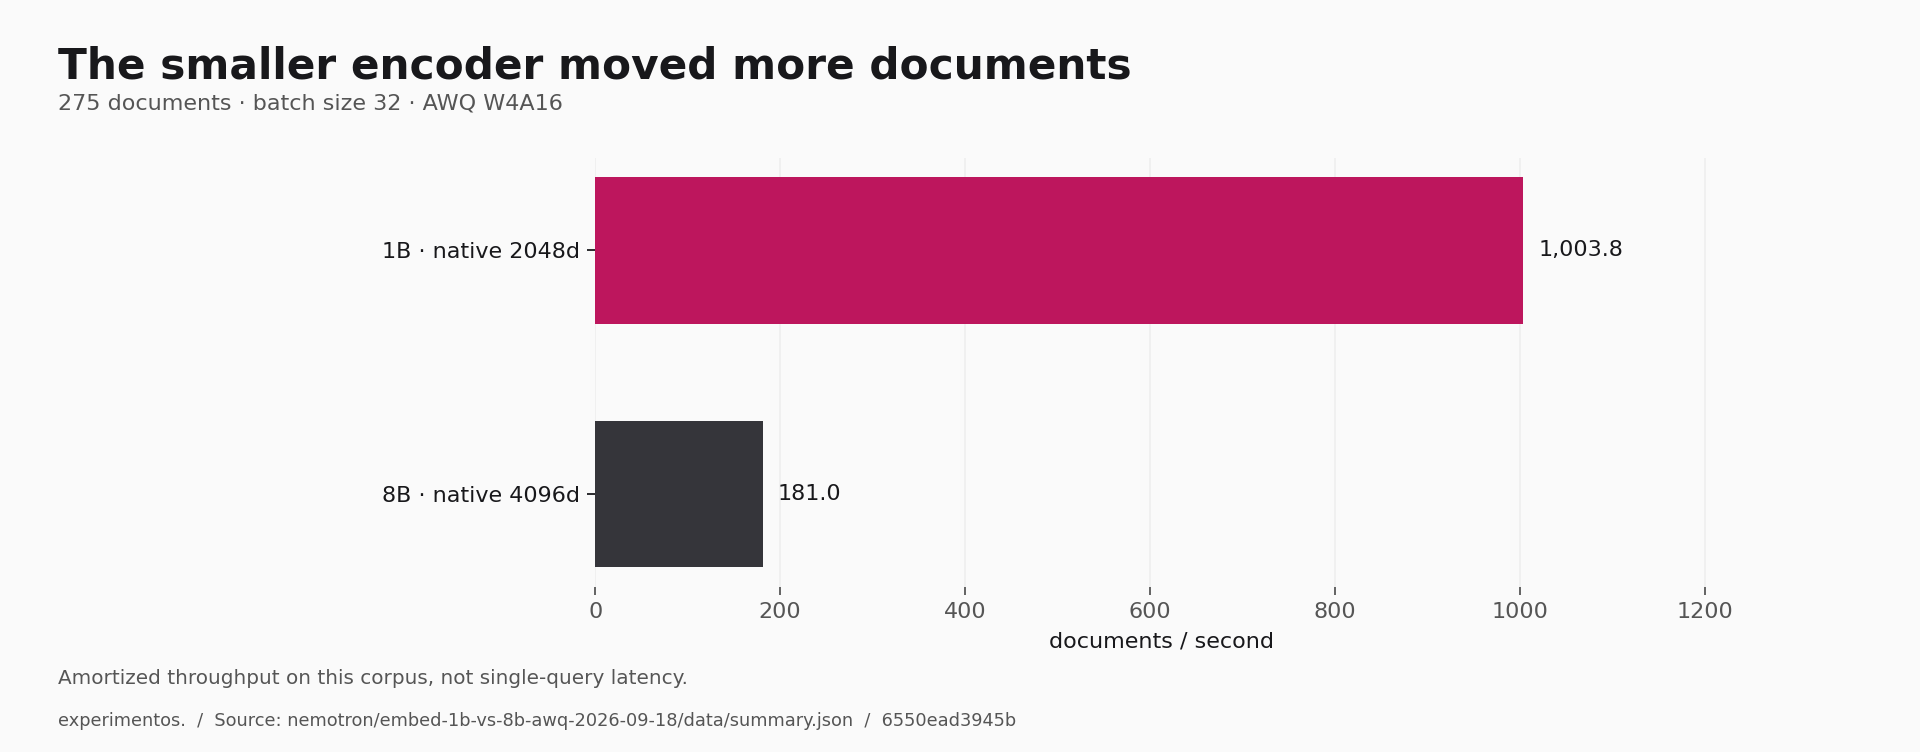
Read the embedding experiment275 documents · batch size 32 · AWQ W4A16
documents / second
Amortized throughput on this corpus, not single-query latency.
| Configuration | Value |
|---|---|
| 1B · native 2048d | 1,003.8 |
| 8B · native 4096d | 181.0 |
Origin: structured measurements. Revision 6550ead3945b.
On Ubuntu CPU, the corrected policy passed 10/10 full-kitchen trials against a same-host retraining control at 7/10.
6 min readThe corrected candidate passed 10/10 paired two-dish trials against a frozen baseline at 0/10.
6 min readThe v3 protocol measured 8/10 full-stage clears versus 0/10 for its paired baseline; the strict gate rejected it.
6 min readThe first-dish baseline produced six successful recorded evaluations across five starting positions, with exact replay.
4 min readOwned frames, bounded controls, saved state, teacher-data export and exact replay form one auditable pipeline.
9 min read