The question
Inbox work needs accurate structured answers and reasonable response times. The benchmark ran the same 50 tasks across local model, runtime and hardware configurations, with thinking on and off, to make that tradeoff visible.
From the original notebook
Which local model should do email triage, extraction and drafting on the home hardware? 17 model/runtime configurations were run through the same 50 tasks (easy 10 + hard 20 + ultra 20), thinking on and off.
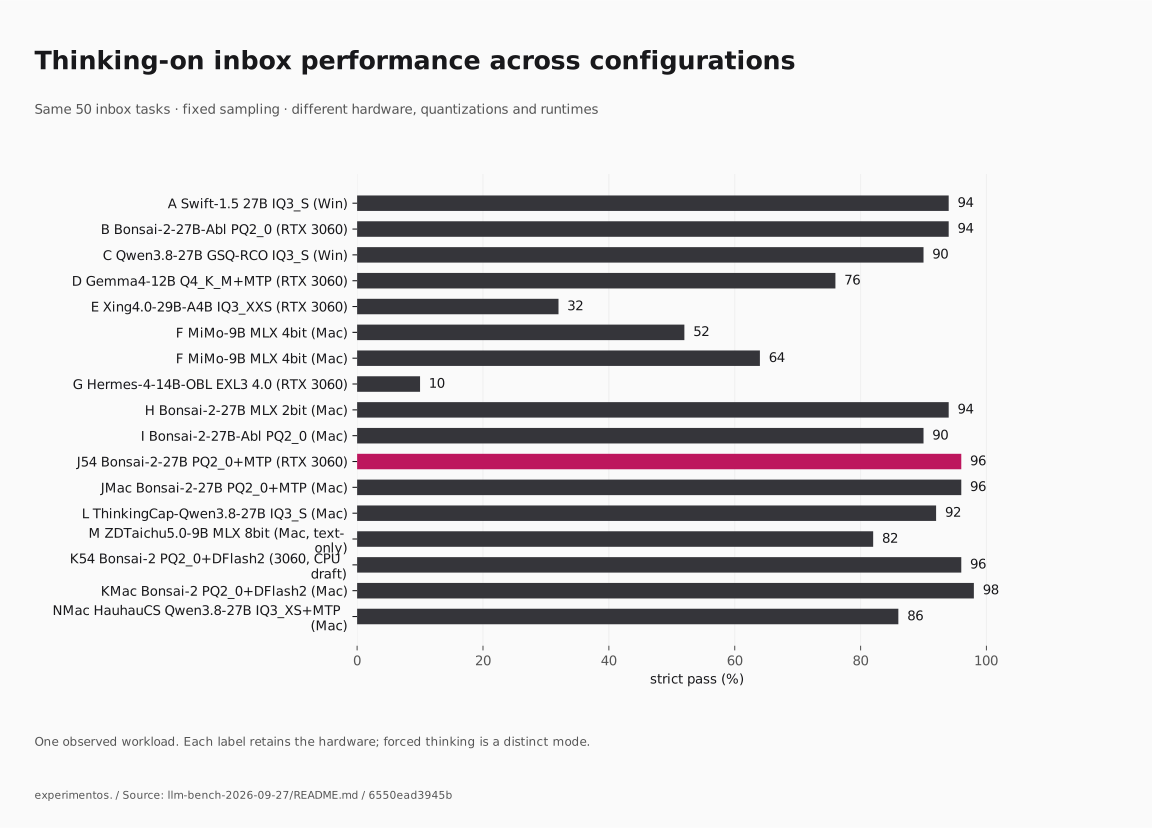
Winner: Bonsai-2-27B PQ2_0 + grafted MTP head (J54) on the .54 RTX 3060: 96% (48/50) strict pass with thinking on,
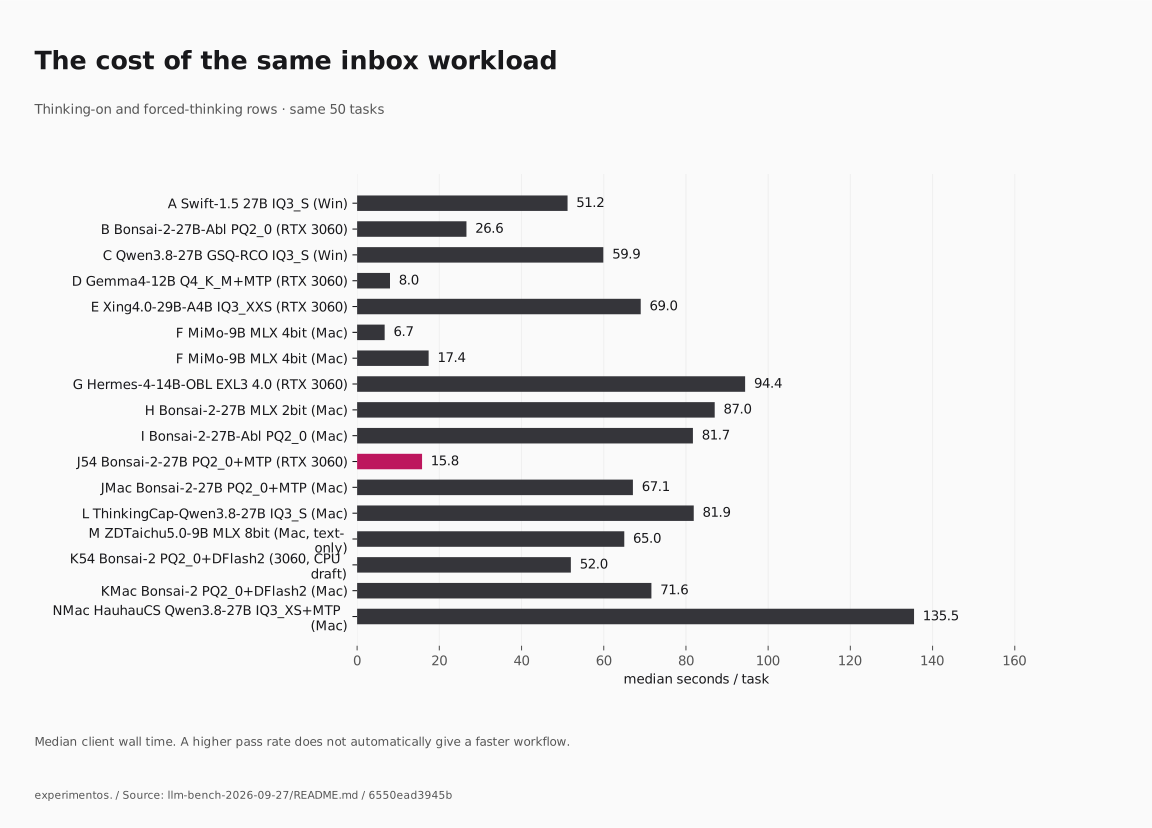
median 15.8 s per task, max 43.3 s (nothing over 120 s), about 52 tok/s decode. It is the only >=94% configuration that is also fast.
Hardware
| Name | Hardware | Runtime(s) used |
|---|---|---|
| .54 | Linux (Ubuntu 24.04), RTX 3060 12 GB, 8 cores, 31 GB RAM. Also runs a vLLM embedder (~2.5 GB VRAM) at all times | PrismML llama.cpp (+MTP patch), stock llama.cpp, Xing fork, TabbyAPI/EXL3 |
| Windows | RTX 3060 12 GB (no other GPU load) | llama.cpp b11177 CUDA 12.4 / PrismML Windows build |
| Mac | Apple M5, 24 GB unified | PrismML llama.cpp Metal, stock llama.cpp, mlx-lm, mlx-vlm |
Hosts are referred to as .54 / Windows / Mac. code/bench.py reads WIN_HOST, LINUX54_HOST and MAC_HOST from the environment; no real addresses are included.
Final table (all 50 tasks, strict grading)
| Model | Mode | Pass % (strict) | easy | hard | ultra | Median s | Max s | >120 s | Decode tok/s | Trunc | VRAM / memory |
|---|---|---|---|---|---|---|---|---|---|---|---|
| A Swift-1.5 27B IQ3_S (Win) | off | 66% (33/50) | 9/10 | 16/20 | 8/20 | 8.9 | 26.4 | 0 | 14.4 | 0 | 12070 MiB VRAM (218 free) |
| A Swift-1.5 27B IQ3_S (Win) | on | 94% (47/50) | 10/10 | 19/20 | 18/20 | 51.2 | 210.1 | 6 | 14.6 | 1 | 12070 MiB VRAM (218 free) |
| B Bonsai-2-27B-Abl PQ2_0 (.54) | off | 72% (36/50) | 10/10 | 14/20 | 12/20 | 4.8 | 15.5 | 0 | 33.6 | 0 | 10135 MiB VRAM (2153 free) |
| B Bonsai-2-27B-Abl PQ2_0 (.54) | on | 94% (47/50) | 10/10 | 17/20 | 20/20 | 26.6 | 68.2 | 0 | 33.6 | 0 | 10135 MiB VRAM (2153 free) |
| C Qwen3.8-27B GSQ-RCO IQ3_S (Win) | off | 68% (34/50) | 10/10 | 16/20 | 8/20 | 9.4 | 55.6 | 0 | 14.8 | 2 | 12070 MiB VRAM (218 free) |
| C Qwen3.8-27B GSQ-RCO IQ3_S (Win) | on | 90% (45/50) | 10/10 | 19/20 | 16/20 | 59.9 | 207.4 | 9 | 14.9 | 5 | 12070 MiB VRAM (218 free) |
| D Gemma4-12B Q4_K_M+MTP (.54) | off | 66% (33/50) | 9/10 | 16/20 | 8/20 | 2.4 | 6.3 | 0 | 62.0 | 0 | 11187 MiB VRAM (1101 free) |
| D Gemma4-12B Q4_K_M+MTP (.54) | on | 76% (38/50) | 8/10 | 16/20 | 14/20 | 8.0 | 40.6 | 0 | 51.6 | 1 | 11187 MiB VRAM (1101 free) |
| E Xing4.0-29B-A4B IQ3_XXS (.54) | off | 36% (18/50) | 9/10 | 7/20 | 2/20 | 7.3 | 39.3 | 0 | 21.1 | 1 | 10921 MiB VRAM (1367 free) |
| E Xing4.0-29B-A4B IQ3_XXS (.54) | on | 32% (16/50) | 9/10 | 6/20 | 1/20 | 69.0 | 157.1 | 17 | 20.7 | 13 | 10921 MiB VRAM (1367 free) |
| F MiMo-9B MLX 4bit (Mac) | off | 52% (26/50) | 10/10 | 14/20 | 2/20 | 6.6 | 18.8 | 0 | 18.7 | 0 | ~7.2-9.4 GB unified (Mac) |
| F MiMo-9B MLX 4bit (Mac) | on | 52% (26/50) | 9/10 | 14/20 | 3/20 | 6.7 | 176.2 | 3 | 20.6 | 3 | ~7.2-9.4 GB unified (Mac) |
| F MiMo-9B MLX 4bit (Mac) | on_forced | 64% (32/50) | 9/10 | 16/20 | 7/20 | 17.4 | 162.9 | 2 | 18.9 | 2 | ~7.2-9.4 GB unified (Mac) |
| G Hermes-4-14B-OBL EXL3 4.0 (.54) | off | 8% (4/50) | 8/10 | 13/20 | 4/20 | 25.5 | 32.1 | 0 | 32.8 | 46 | 10669 MiB VRAM (1619 free; Q6 cache, chunk 512) |
| G Hermes-4-14B-OBL EXL3 4.0 (.54) | on | 10% (5/50) | 8/10 | 10/20 | 5/20 | 94.4 | 106.5 | 0 | 13.1 | 40 | 10669 MiB VRAM (1619 free; Q6 cache, chunk 512) |
| H Bonsai-2-27B MLX 2bit (Mac) | off | 62% (31/50) | 10/10 | 13/20 | 8/20 | 14.9 | 50.4 | 0 | 9.9 | 0 | 9966 MB footprint (Mac) |
| H Bonsai-2-27B MLX 2bit (Mac) | on | 94% (47/50) | 10/10 | 18/20 | 19/20 | 87.0 | 260.2 | 16 | 9.8 | 0 | 9966 MB footprint (Mac) |
| I Bonsai-2-27B-Abl PQ2_0 (Mac) | off | 72% (36/50) | 10/10 | 14/20 | 12/20 | 12.0 | 51.3 | 0 | 11.6 | 0 | ~10.0 GB footprint (Mac) |
| I Bonsai-2-27B-Abl PQ2_0 (Mac) | on | 90% (45/50) | 10/10 | 16/20 | 19/20 | 81.7 | 246.7 | 17 | 11.0 | 0 | ~10.0 GB footprint (Mac) |
| J54 Bonsai-2-27B PQ2_0+MTP (.54) | off | 66% (33/50) | 10/10 | 14/20 | 9/20 | 3.8 | 9.7 | 0 | 53.0 | 0 | 10963 MiB VRAM (1325 free) |
| J54 Bonsai-2-27B PQ2_0+MTP (.54) | on | 96% (48/50) | 10/10 | 18/20 | 20/20 | 15.8 | 43.3 | 0 | 52.0 | 0 | 10963 MiB VRAM (1325 free) |
| JMac Bonsai-2-27B PQ2_0+MTP (Mac) | off | 66% (33/50) | 10/10 | 14/20 | 9/20 | 13.1 | 50.8 | 0 | 12.1 | 0 | ~10.0 GB footprint (Mac) |
| JMac Bonsai-2-27B PQ2_0+MTP (Mac) | on | 96% (48/50) | 10/10 | 19/20 | 19/20 | 67.1 | 172.6 | 10 | 11.3 | 0 | ~10.0 GB footprint (Mac) |
| L ThinkingCap-Qwen3.8-27B IQ3_S (Mac) | off | 68% (34/50) | 10/10 | 16/20 | 8/20 | 23.1 | 134.2 | 2 | 6.4 | 2 | 12.6 GB weights, footprint ~9.9 GB + paging (Mac) |
| L ThinkingCap-Qwen3.8-27B IQ3_S (Mac) | on | 92% (46/50) | 10/10 | 18/20 | 18/20 | 81.9 | 310.9 | 14 | 6.2 | 0 | 12.6 GB weights, footprint ~9.9 GB + paging (Mac) |
| M ZDTaichu5.0-9B MLX 8bit (Mac, text-only) | off | 46% (23/50) | 10/10 | 11/20 | 2/20 | 6.7 | 33.2 | 0 | 13.5 | 0 | 12 GB footprint peak (Mac) |
| M ZDTaichu5.0-9B MLX 8bit (Mac, text-only) | on | 82% (41/50) | 10/10 | 17/20 | 14/20 | 65.0 | 227.1 | 10 | 13.3 | 1 | 12 GB footprint peak (Mac) |
| K54 Bonsai-2 PQ2_0+DFlash2 (.54, draft on CPU) | off | 66% (33/50) | 10/10 | 14/20 | 9/20 | 8.5 | 31.5 | 0 | 14.8 | 0 | 11203 MiB VRAM (1085 free; draft on CPU) |
| K54 Bonsai-2 PQ2_0+DFlash2 (.54, draft on CPU) | on | 96% (48/50) | 10/10 | 19/20 | 19/20 | 52.0 | 243.7 | 7 | 14.1 | 1 | 11203 MiB VRAM (1085 free; draft on CPU) |
| KMac Bonsai-2 PQ2_0+DFlash2 (Mac) | off | 66% (33/50) | 10/10 | 14/20 | 9/20 | 13.1 | 57.4 | 0 | 12.0 | 0 | ~9.3 GB weights, footprint ~8.5-10 GB (Mac) |
| KMac Bonsai-2 PQ2_0+DFlash2 (Mac) | on | 98% (49/50) | 10/10 | 19/20 | 20/20 | 71.6 | 172.2 | 11 | 11.6 | 0 | ~9.3 GB weights, footprint ~8.5-10 GB (Mac) |
| N54 HauhauCS Qwen3.8-27B IQ3_XS+MTP (.54, partial offload) | off | 60% (30/50) | 10/10 | 12/20 | 8/20 | 48.4 | 184.8 | 8 | 2.0 | 0 | 11221 MiB VRAM (1067 free; -ngl 44/65, rest on CPU) |
| NMac HauhauCS Qwen3.8-27B IQ3_XS+MTP (Mac) | off | 62% (31/50) | 10/10 | 13/20 | 8/20 | 17.6 | 60.7 | 0 | 7.6 | 0 | Mac RSS 12.8 GB (footprint 2.1 GB, weights mmap) |
| NMac HauhauCS Qwen3.8-27B IQ3_XS+MTP (Mac) | on | 86% (43/50) | 10/10 | 18/20 | 15/20 | 135.5 | 467.6 | 27 | 6.8 | 5 | Mac RSS 12.8 GB (footprint 2.1 GB, weights mmap) |
Notes: sampling for every request was temperature 0.2, top_p 0.95, top_k 20, seed 42. Thinking ON used max_tokens 3000; OFF used 800.
Requests ran one at a time. Wall time is measured at the client. Full per-task detail, repeat runs and caveats are in summary.md.
Winning configuration: exact J launch command (.54)
Binary: PrismML llama.cpp (prism-b10685 source) plus scripts/0001-qwen35-mtp-hadamard-inverse.patch, built with
scripts/build_prismml_mtp.sh (CUDA 12.8, sm_86). Model: Bonsai-2-27B-PQ2_0-MTP.gguf from
decent-jawfish/bonsai-2-27b-mtp (sha256 78df4279d40ebebdccfd2dae0e9d4847afee52e94f48f3542ae9437220dbd847).
As benchmarked (2026-09-27, -c 16384):
./llama-server -m Bonsai-2-27B-PQ2_0-MTP.gguf --alias bonsai-27b-pq2-mtp --host 0.0.0.0 --port 8801 \
  -ngl 999 -fa on -c 16384 -np 1 -ctk q8_0 -ctv q8_0 --jinja \
  --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.05 \
  --chat-template-kwargs '{"reasoning_effort": "medium"}' \
  --spec-type draft-mtp --spec-draft-n-max 2
Production since 2026-09-28: same command with -c 28672 ... -ctkd q8_0 -ctvd q8_0 -fit off. That is the largest context that stays fully on the GPU with at least 300 MiB free (see below).
Max-context search on .54 (2026-09-28)
Conditions: fully on the GPU (-ngl 999, -fit off, no CPU offload), draft MTP on (--spec-draft-n-max 2), q8_0 KV for the target and the draft (-ctk/-ctv/-ctkd/-ctvd q8_0), -fa on, -np 1, with the vLLM embedder resident (2548 MiB).
A setting only counts if the server loads and a synthetic prompt filling about 90% of the context completes, with at least 300 MiB of GPU memory free at peak. The script is scripts/ctx_test.py and the raw results are in results/ctx_search_54.jsonl.
Each extra 2048 tokens of context costs about 46 MiB.
| Model | -c | Loads | 90% prompt (tokens) | Prompt tok/s | Decode tok/s @ 90% fill | Decode tok/s (short, JSON) | Draft accept | VRAM used, loaded (MiB, whole GPU) | Min free during prompt (MiB) | Counts (>=300 MiB free) |
|---|---|---|---|---|---|---|---|---|---|---|
| Abliterated-v2 PQ2_0 MTP | 16384 | OK | 14769 (90.1%) | 496.8 | 35.9 | 56.2 | 0.92 | 11059 | n/a (first run) | no, margin |
| Bonsai-2-27B PQ2_0 MTP | 16384 | OK | 14769 (90.1%) | 492.6 | 37.1 | 57.1 | 0.933 | 10963 | 933 | yes |
| Bonsai-2-27B PQ2_0 MTP | 24576 | OK | 22107 (90.0%) | 474.8 | 34.3 | 56.8 | 0.933 | 11333 | 563 | yes |
| Bonsai-2-27B PQ2_0 MTP | 28672 | OK | 25817 (90.0%) | 465.8 | 33.8 | 56.7 | 0.933 | 11517 | 379 | yes |
| Bonsai-2-27B PQ2_0 MTP | 30720 | OK | 27636 (90.0%) | 460.4 | 33.4 | 56.8 | 0.933 | 11609 | 287 | no, margin |
| Bonsai-2-27B PQ2_0 MTP | 32768 | OK | 29484 (90.0%) | 456.3 | 32.5 | 56.9 | 0.933 | 11701 | 195 | no, margin |
| Abliterated-v2 PQ2_0 MTP | 26624 | OK | 23977 (90.1%) | 470.4 | 33.6 | 56.0 | 0.92 | 11521 | 375 | yes |
| Abliterated-v2 PQ2_0 MTP | 28672 | OK | 25817 (90.0%) | 465.0 | 33.6 | 55.7 | 0.92 | 11613 | 283 | no, margin |
- Bonsai-2-27B PQ2_0 MTP: max safe
-c 28672(379 MiB free at peak). 30720 and 32768 also ran but left only 287 and 195 MiB free. - Abliterated-v2 PQ2_0 MTP: max safe
-c 26624(375 MiB free). The file is about 100 MB larger, so it fits one step less. - For comparison, the Windows 3060 has no embedder and reaches
-c 77824.
Abliterated variant with MTP
The bench’s “B” model was Ternary-Bonsai-2-27B-Abliterated-PQ2_0.gguf (no MTP). Kept on .54 for later use (not serving) is
BoldingBuilds/Ternary-Bonsai-2-27B-Abliterated-v2-PQ2_0-MTP-GGUF,
file Ternary-Bonsai-2-27B-Abliterated-v2-PQ2_0-MTP.gguf (sha256 a4e4c7b578131595c1694354bd6c74d00920df1f5082647a6126899753ebebf8, verified).
Its model card says v2 fixes v1’s thinking-mode blank answers. It loads with --spec-type draft-mtp on the same binary: 56 tok/s on a short JSON generation (draft acceptance 0.92) and 33.6 tok/s at 90% of a 26.6K context. It was not run through the 50-task suite.
Layout
code/:bench.py(runner),tasks.py/tasks_hard.py/tasks_ultra.py(prompts + graders),summarize.py,combined.py,final_table.py,vram_stats.py,speedtest.pyresults/: raw JSONL for every run (results_<X>.jsonl= easy,results_hard_<X>.jsonl,results_ultra_<X>.jsonl; letter = model key inbench.py), plusctx_search_54.jsonlsummary.md: full generated report (per-suite and per-task tables, repeat runs, caveats);final_table.md: the table abovescripts/: MTP patch, build script, and the context-search harness
To reproduce: cd code && LINUX54_HOST=<host> python3 bench.py --model J --modes off,on --suite tasks_hard --out results_hard_J.jsonl (--suite is tasks, tasks_hard or tasks_ultra; --base overrides the endpoint).
summarize.py and combined.py read the results*.jsonl files from the working directory.
Clean-up after the bench (2026-09-28)
Only Bonsai models were kept (base MTP on .54, Windows and Mac, plus the abliterated v2 MTP on .54). The Swift/GSQ/Gemma/Xing/MiMo/Hermes/ThinkingCap/ZDTaichu/HauhauCS weights were deleted.
Keep exploring
Original experiment record. Workstation paths have been generalized. Detailed measurements below retain their original workload and validation boundaries.