The question
The speech stack exceeded the target memory envelope before staging. This hardening experiment verified protected layers and quantized projections, then measured staged memory on the hardware actually available.
From the original notebook
Date: 2026-09-18. Repo: groxaxo/moss-tts-hq4-quant, branch
fix/release-reproducibility-hardening-v2 at 7982ede
(7982edee4f10b293db8a7e4d7293661a69679692), base main at bfd27b1.
PR #1 (draft): “Harden HQ4 release provenance, validation, and 12GB staging
claims”. Workstation checkout: WORKSTATION/moss-tts-hq4-quant.
Question answered: do the PR’s “local GPU gates before merge” pass on the
Ubuntu workstation — py_compile, bash -n, verify_quantization_map.py,
and the staged 12 GB inference path?
Measured result: all listed gates pass. Verifier: 252/252 INT4
projections, 211 protected BF16 params, bits=4 / g=128 / sym=true.
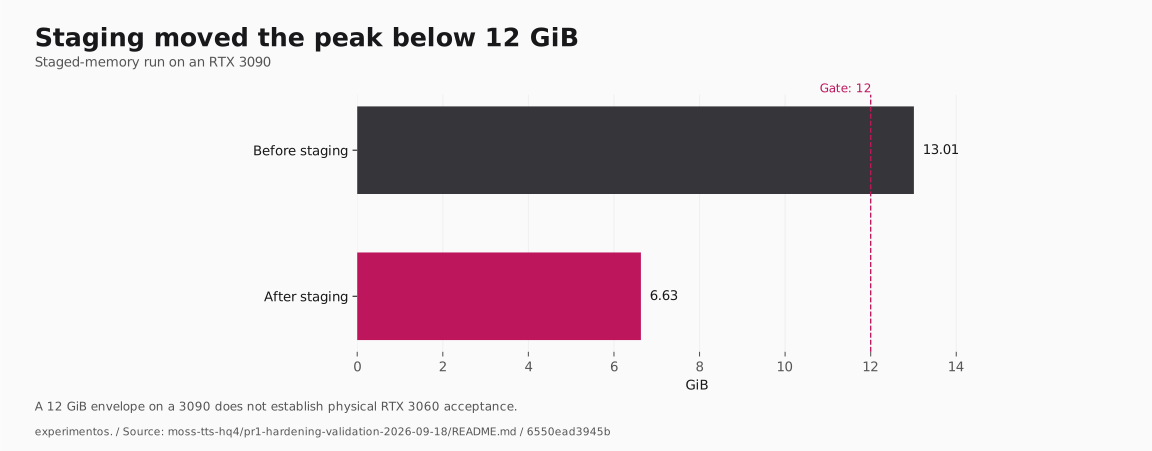
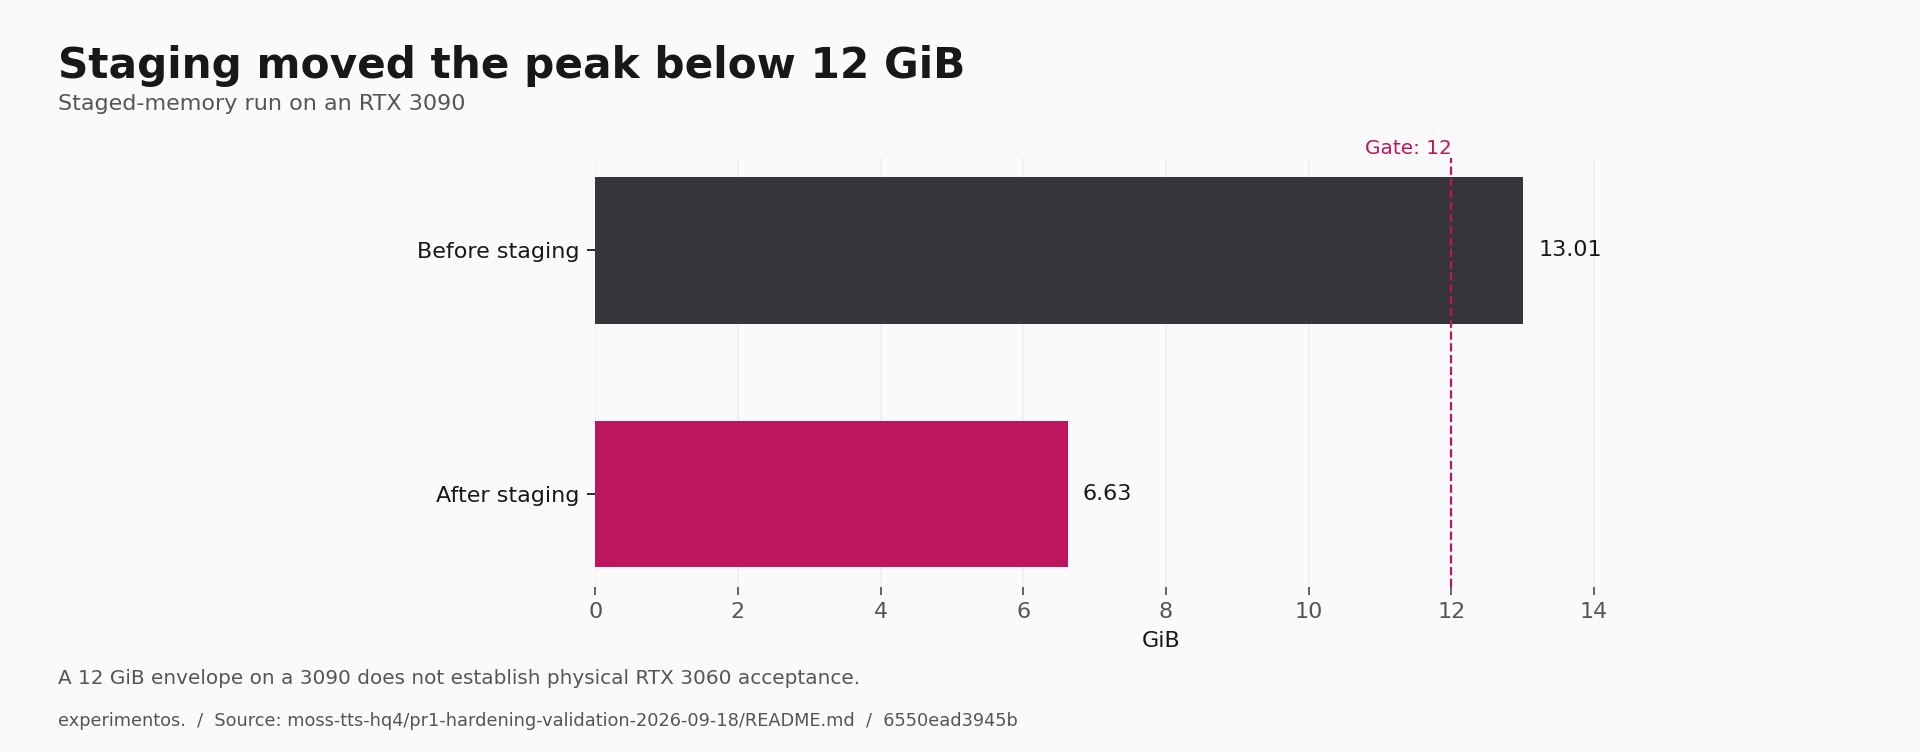
Staged text-only run under a 0.5 memory fraction on one RTX 3090 peaks at
6.63 GiB (vs 13.01 GiB pre-staging), with the generator fully parked on
CPU (0.01 GiB) during codec decode. No physical RTX 3060 exists on this host,
so the true 3060 acceptance run remains open by design.
Workflow
flowchart LR
    A[Locate repo +<br/>fetch PR branch] --> B[Checkout 7982ede<br/>review 12-file diff]
    B --> C[Gate 1: py_compile<br/>4 tools]
    C --> D[Gate 2: bash -n<br/>4 scripts]
    D --> E[Gate 3: verifier<br/>GPU 2, real artifact]
    E --> F[Gate 4: staged run<br/>memfrac 0.5, GPU 1]
    F --> G[Phase-VRAM probe<br/>run_single + rec]
    G --> H[Quantizer probes<br/>refusal + recipe]
    H --> I[This record<br/>+ PR update]
Step outcomes (observed, in order):
| # | Action | Evidence | Outcome |
|---|---|---|---|
| 1 | Fetched origin, checked out PR tip | git log, diffstat 12 files +268/-138 |
On 7982ede, clean tree |
| 2 | py_compile on 4 touched tools |
Console PY_COMPILE_OK |
Pass |
| 3 | bash -n on 4 ops scripts |
Console BASH_N_OK x4 |
Pass |
| 4 | Verifier on GPU 2 vs real artifact | verifier-tail | VERIFY PASSED, exit 0 |
| 5 | Staged run, memfrac 0.5, GPU 1 | sample, JSON | Exit 0, peak 6.647 GiB |
| 6 | Phase-VRAM capture via run_single(rec) |
sample, phases below | Exit 0, peak 6.634 GiB |
| 7 | Quantizer refusal/recipe probes (CPU-only) | Console *_OK x5 |
All pass |
| 8 | Voice-test flags + wav sanity | --help, peak 0.79, no NaN, not silent |
Pass |
What was tested
Environment: 3× RTX 3090 24 GB (driver 595.58.03), Python 3.12.3,
torch 2.9.1+cu128, transformers 5.0.0, auto-round 0.15.1 (see
versions). Runtime venv, weights, and artifact live under
WORKSTATION/MOSS-TTS — moss-tts-hq4-quant ships code only, so the GPU gates
ran the PR-branch scripts with the MOSS-TTS venv and absolute model paths.
| Gate | Command (equivalent) | Result |
|---|---|---|
| py_compile | python3 -m py_compile tools/{infer_hybrid_3060,quantize_moss_autoround_awq,test_native_voice_hq4,verify_quantization_map}.py |
Pass |
| bash -n | hq4_chain_gpu2.sh, monitor-hq4.sh, both retry-wrapper-hq4-fast.sh |
Pass x4 |
| Verifier | CUDA_VISIBLE_DEVICES=2 … verify_quantization_map.py --model artifacts/… |
VERIFY PASSED, exit 0 |
| Staged 12 GB | infer_hybrid_3060.py … --memory-fraction 0.5 --seed 1234 (text-only) |
Exit 0, 5.36 s audio, RTF 1.76 |
Verifier detail: 36 layers → 252/252 quantized projections, 252/252 qweight
tensors, 211 protected BF16 parameters, quant_method=auto-round.
Phase VRAM (GiB, allocated / peak), second run:
| Phase | Allocated | Peak |
|---|---|---|
| load | 6.237 | 6.237 |
| prefill_ready | 6.237 | 6.237 |
| generate | 6.250 | 6.590 |
| generator_parked_cpu | 0.013 | 6.590 |
| decode | 6.625 | 6.634 |
Overall peak 6.634 GiB — the pre-staging benchmark peaked at 13.01 GiB
with generator+codec coexisting at decode (see
benchmark_results_hq4.json in the artifact dir). The CPU-parking fix
recovers ~6.4 GiB at decode.
Quantizer probes (CPU-only, throwaway dirs under /tmp, no GPU, no quant
run): namespace remap, missing-calibration FileNotFoundError pointing at
tools/build_moss_calibration.py, untracked-export refusal, stale-export
fingerprint-mismatch refusal, and recipe contents (cal SHA256, W4A16/sym
settings, dep versions) — all pass.
Runs and timing
| Run | GPU | Result | Wall |
|---|---|---|---|
Verifier vs MOSS-TTS-v1.5-HQ4-AWQ |
2 (as cuda:0) | VERIFY PASSED | ~40 s incl. load |
Staged envelope (staged-12gb-envelope.wav) |
1 (as cuda:0), memfrac 0.5 | Exit 0, 101 tokens | 19.2 s total, 9.4 s gen |
Phase capture (phase-capture-run.wav) |
1 (as cuda:0), memfrac 0.5 | Exit 0 | ~20 s |
Limits and reproduction boundary
- No RTX 3060 on this host. The 12 GB result is the documented
--memory-fraction 0.5surrogate on a 3090, not a physical 3060 run. The PR docs already state this correctly; this record does not upgrade the claim to “verified”. - The tested artifact predates
quant_recipe.json(expected — only new quant runs emit it). A full re-quant was not run (1 h+ GPU job); the recipe/fingerprint logic was validated via the refusal-path probes above. ops/hq4-quant/*.shstillcd WORKSTATION/MOSS-TTS— pre-existing, outside this PR’s scope, noted for a follow-up.- The private Hugging Face model-card sync was reported outstanding in the handoff and was not attempted here.
- Rerun: scripts/rerun-gates.sh (
RUN_GPU=1for the GPU gates;REPO/VENV/MODEL/CODECoverridable). Machine-readable results: data/validation.json.
No merge or deployment performed; PR #1 left draft and open.
Keep exploring
Original experiment record. Workstation paths have been generalized. Detailed measurements below retain their original workload and validation boundaries.