Journal

Moving speech decode onto the GPU

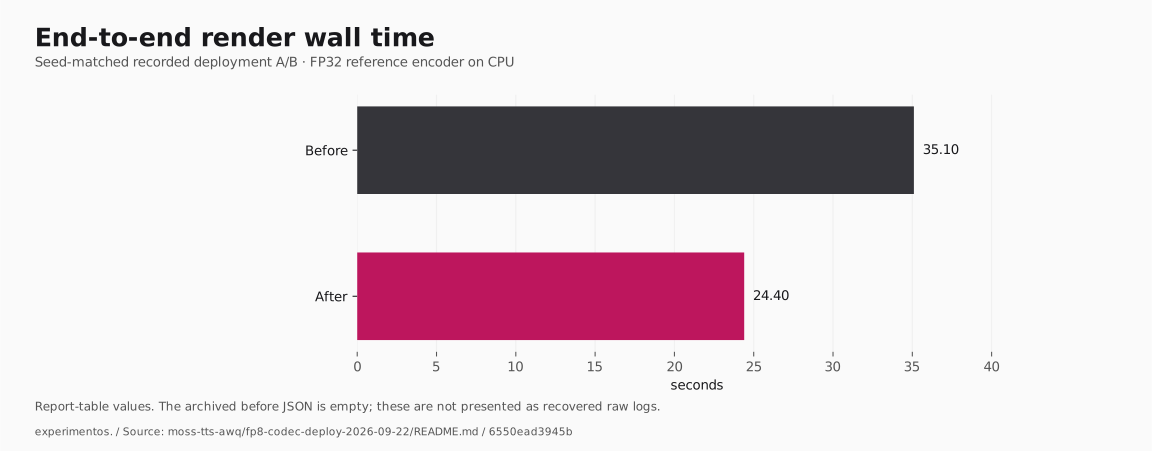
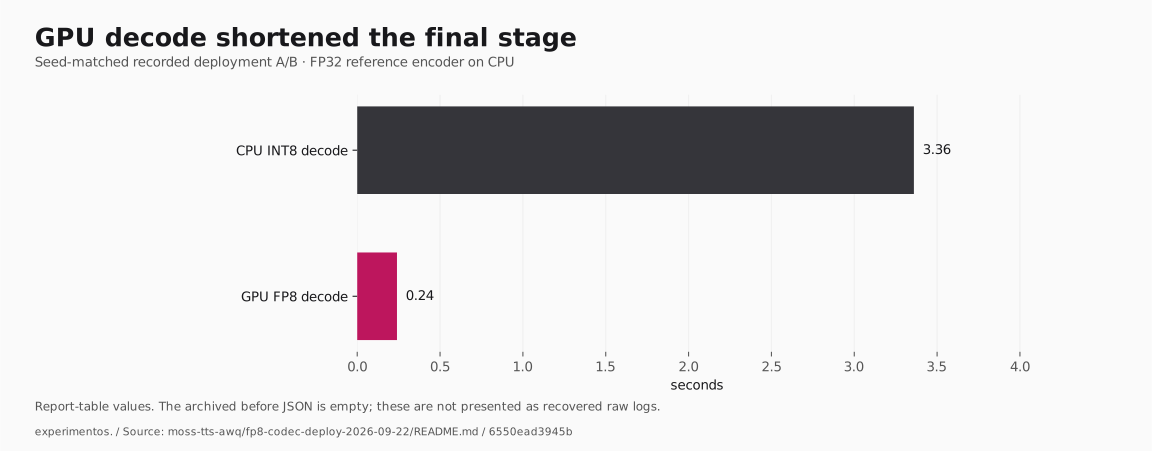
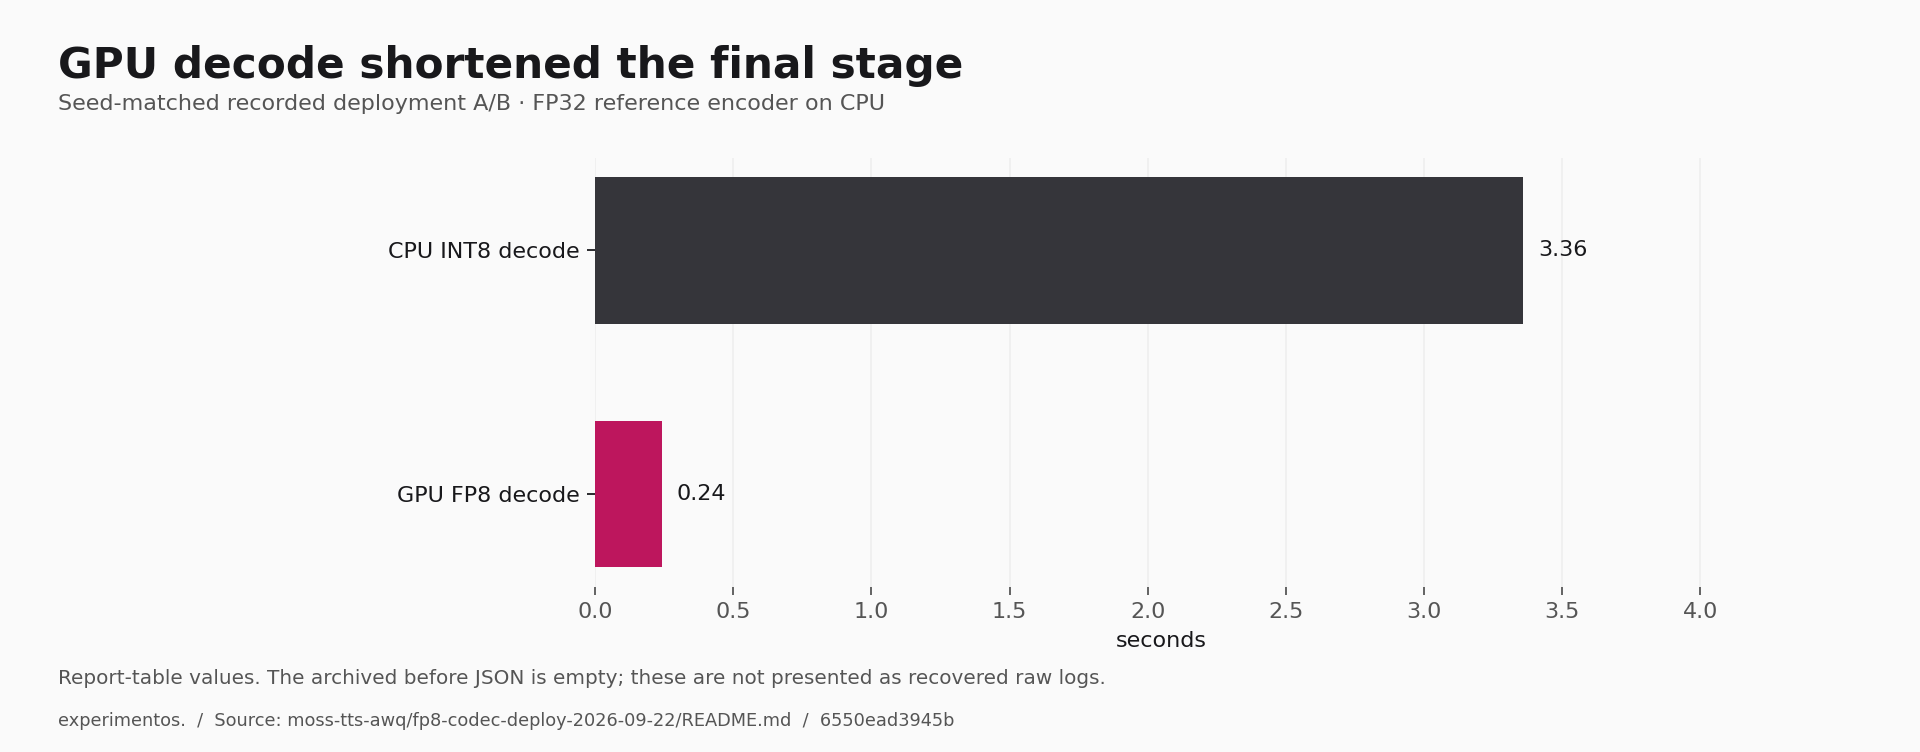
Decode dropped from 3.36 seconds to 0.24; total render wall time dropped from 35.1 to 24.4 seconds.

Vlad / experimentos.
The boundary

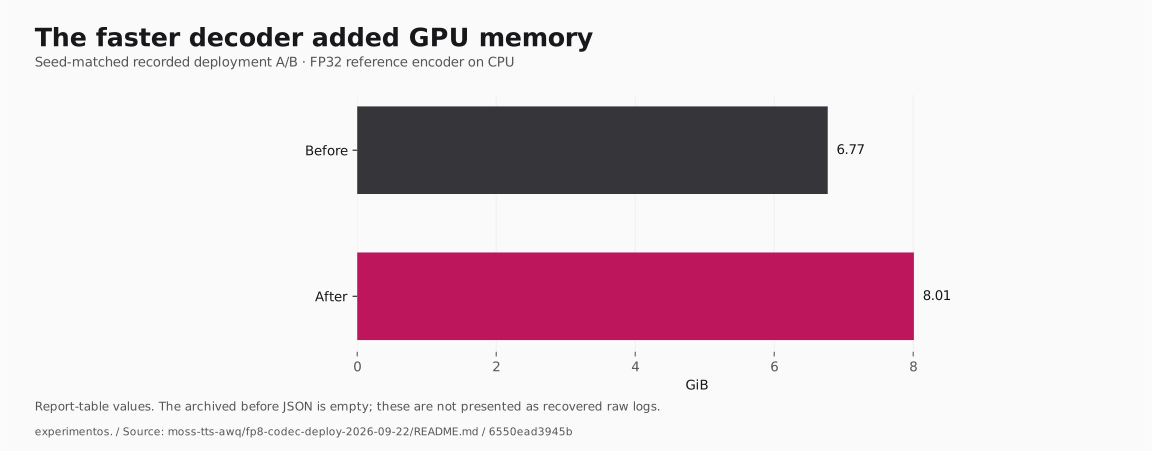
The decoder adds resident GPU memory. Reference encoding stays FP32 on CPU; the seed-matched A/B does not cover every voice.

Measurements

Recorded result

GPU decode shortened the final stage

Seed-matched recorded deployment A/B · FP32 reference encoder on CPU

GPU decode shortened the final stageCPU INT8 decode: 3.36 seconds; GPU FP8 decode: 0.24 seconds. Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.CPU INT8 decode3.36CPU INT8 decode: 3.36 secondsGPU FP8 decode0.24GPU FP8 decode: 0.24 seconds0seconds
  1. CPU INT8 decode3.36
  2. GPU FP8 decode0.24

seconds

Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.

View data & source
GPU decode shortened the final stage · seconds
ConfigurationValue
CPU INT8 decode3.36
GPU FP8 decode0.24

Origin: reported table. Revision 6550ead3945b.

Download measurement metadata (JSON)
Recorded result

End-to-end render wall time

Seed-matched recorded deployment A/B · FP32 reference encoder on CPU

End-to-end render wall timeBefore: 35.10 seconds; After: 24.40 seconds. Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.Before35.10Before: 35.10 secondsAfter24.40After: 24.40 seconds0seconds
  1. Before35.10
  2. After24.40

seconds

Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.

View data & source
End-to-end render wall time · seconds
ConfigurationValue
Before35.10
After24.40

Origin: reported table. Revision 6550ead3945b.

Download measurement metadata (JSON)
Recorded result

The faster decoder added GPU memory

Seed-matched recorded deployment A/B · FP32 reference encoder on CPU

The faster decoder added GPU memoryBefore: 6.77 GiB; After: 8.01 GiB. Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.Before6.77Before: 6.77 GiBAfter8.01After: 8.01 GiB0GiB
  1. Before6.77
  2. After8.01

GiB

Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.

View data & source
The faster decoder added GPU memory · GiB
ConfigurationValue
Before6.77
After8.01

Origin: reported table. Revision 6550ead3945b.

Download measurement metadata (JSON)

The question

Moving the final audio decode onto the GPU shortened both that stage and total render time. The deployment A/B also records the extra GPU memory, so the speed improvement can be weighed against its cost.

From the original notebook

Took the FP8 codec validated in codec-roundtrip-fp8-2026-09-21 and deployed it in the live production daemon on the .54 RTX 3060: the artifact dequantizes to BF16 at load, the encoder half is dropped (decode-only, ~1.6 GiB), and the decoder stays resident on cuda:0 next to the warm generator (6.37 GiB). Reference encoding stays on the FP32/CPU codec (the validated clone fix; the FP8 encoder remains untested for conditioning).

Production code: groxaxo/moss54 commit 40ac7f0 (ops/moss54d/moss54d.py, flag --codec-fp8).

Measured (A/B, seed 1234, same reference, .54 RTX 3060 12 GB)

Metric Before (CPU fp32 decode) After (FP8 GPU decode)
decode_time_s (clone) 3.36 0.24 (14×)
decode_time_s (default voice) 2.76 0.23
gen_time_s 22.9 22.91–22.94 (unchanged)
wall_s per render (clone) 35.1 24.4
new_tokens / duration_s 193 / 12.72 identical
audio_health flags all false all false
daemon VRAM steady 6.77→8.01 GiB torch-reserved (net +1.6)

Verification per the golden protocol: identical sample counts and token/duration parity (PCM mean-abs diff 0.0018 — codec-precision level); ASR A/B (whisperx medium es) identical transcripts before/after in both voices (0.0625/0.0625, 0.0938/0.0938 — residual = transcriber mishears present in both). First post-restart render shows warmup-inflated gen_time; repeat runs are the reportable number.

Contents

  • docs/before_results.json, docs/after_results.json — raw A/B metrics.
  • docs/wer_ab.json — whisperx transcripts + WER, all four files.
  • samples/ — the four A/B WAVs.
  • scripts/render_ab.py — the exact harness (POST /v1/audio/speech).

Boundaries

Single seed, one reference, one text per voice; decode speedup scales with audio length. RTF gen unchanged (7–8 tok/s). The FP8 encoder path is deliberately NOT exercised. No blind ABX listening — parity rests on the round-trip shootout + identical ASR transcripts + unchanged speaker path.

Keep exploring

Original experiment record. Workstation paths have been generalized. Detailed measurements below retain their original workload and validation boundaries.

Follow the evidence

From notebook to finding.

This story is based on the archived experiment at revision 6550ead3945b. Original timestamps, workloads and qualification limits belong to that record.
Original GitHub record
Supporting notebooks (1)

GitHub source links require access to the private archive. The readable notes and aggregate chart exports are included here.

Back to the journal Follow via RSS