The question
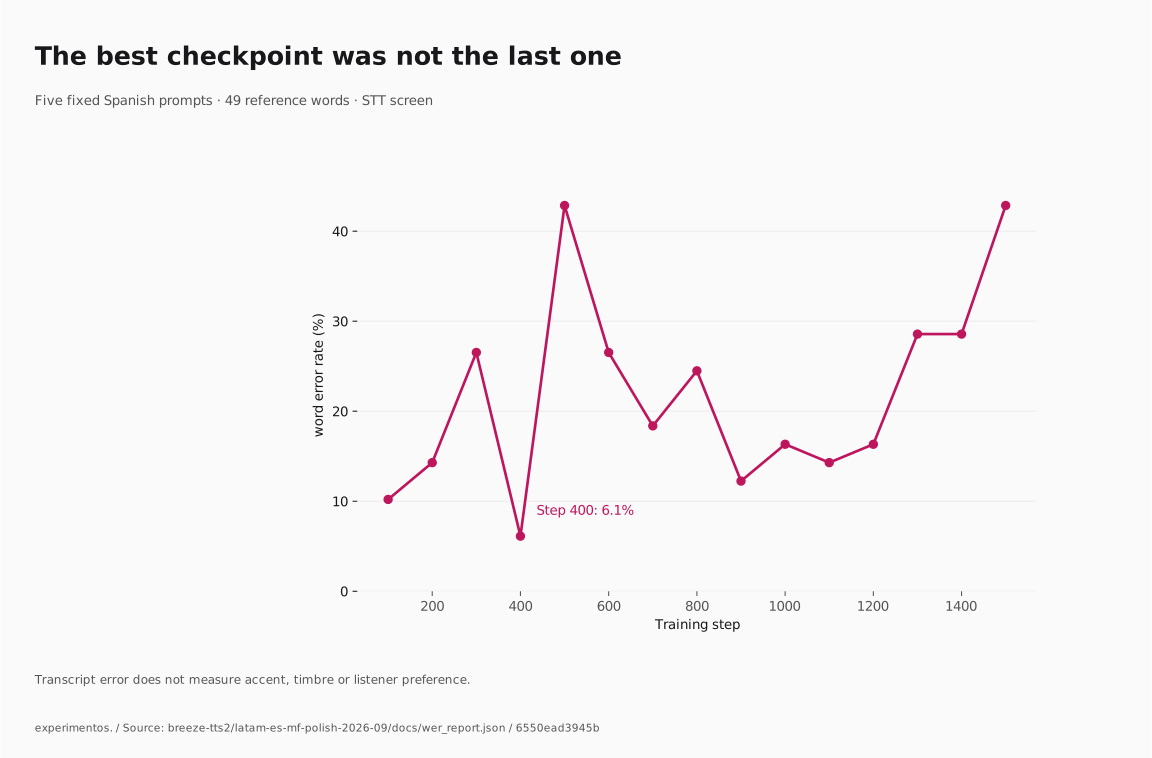
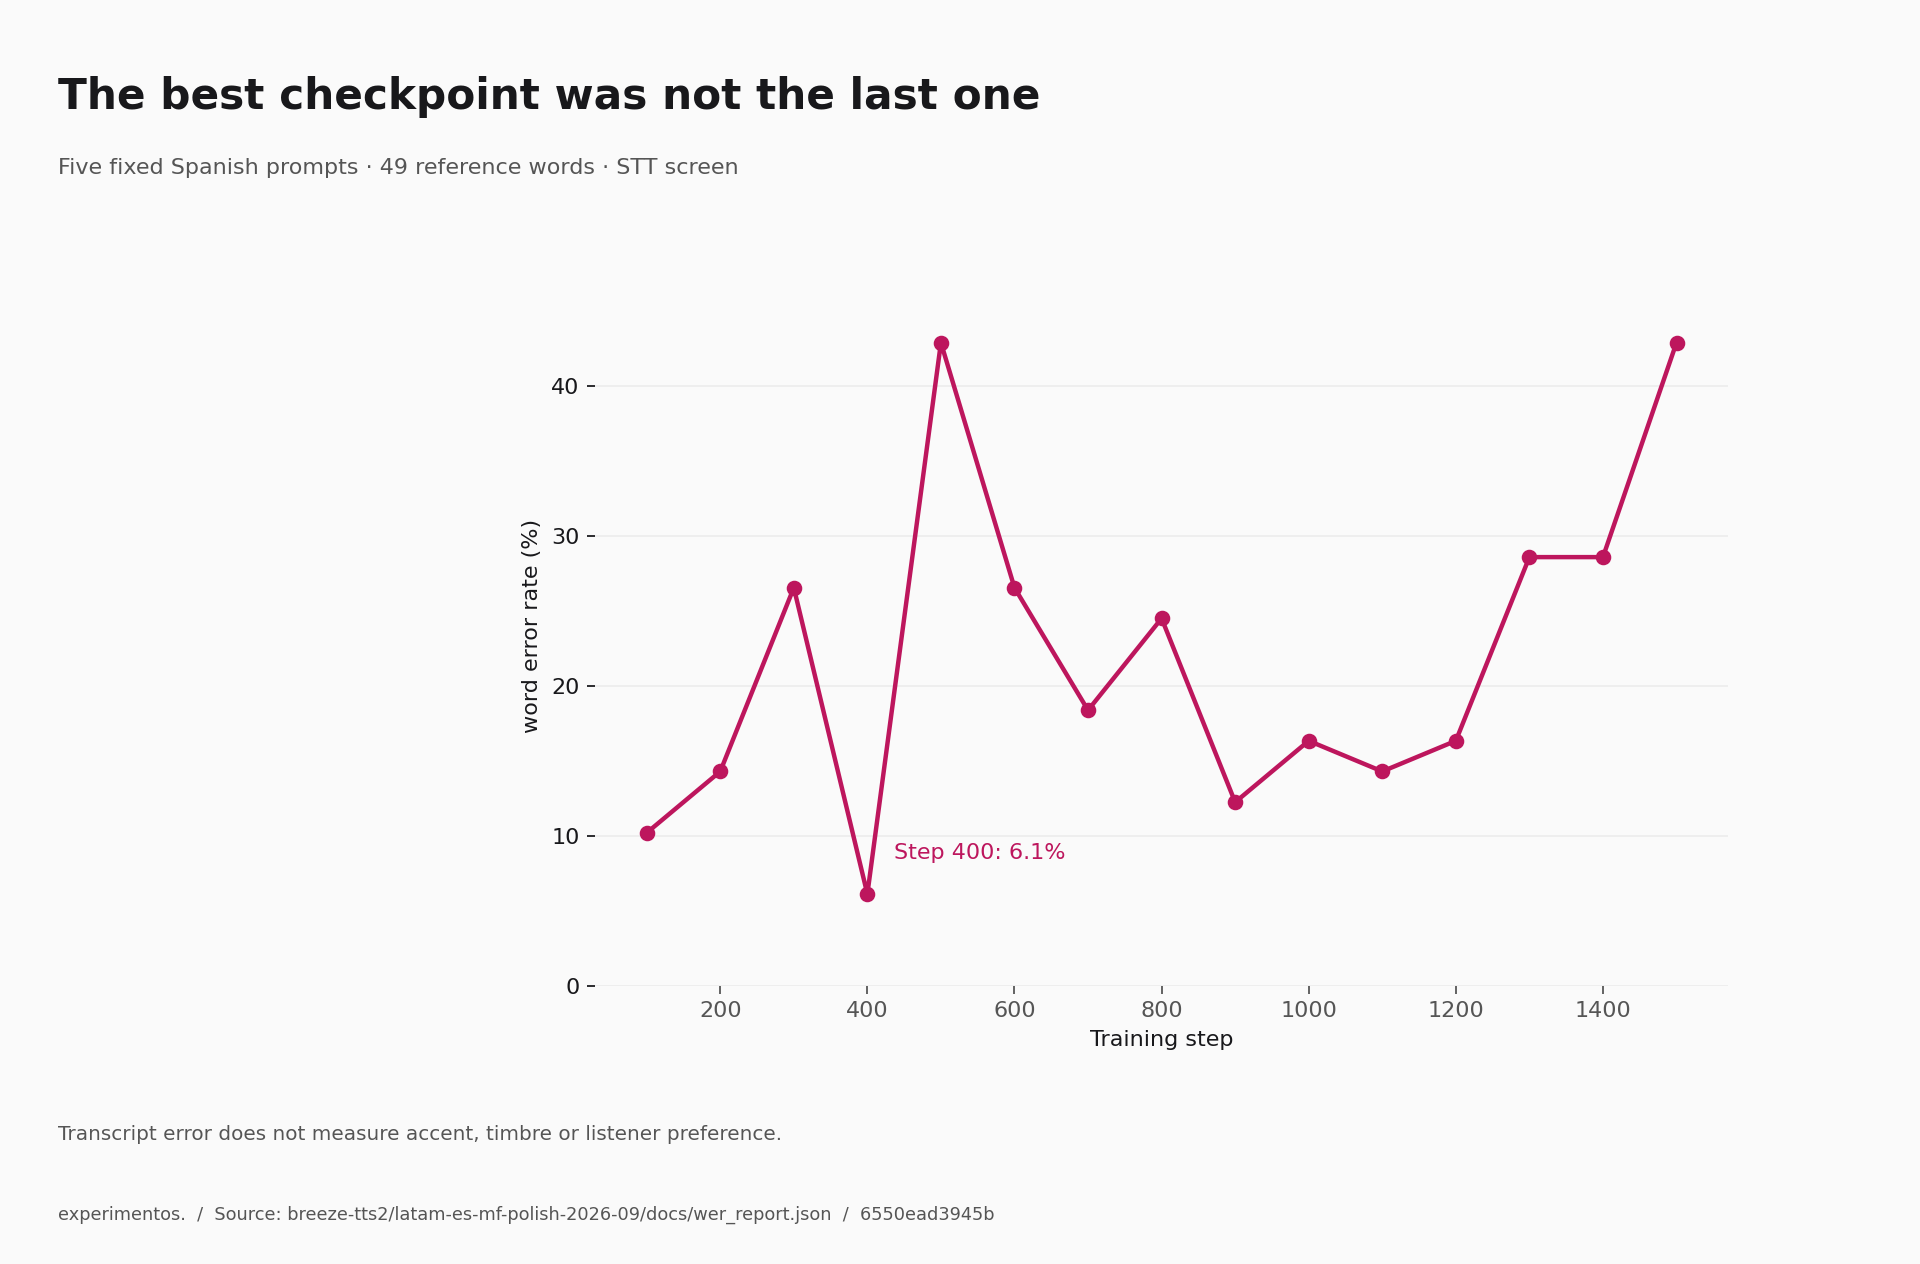
Training longer did not make every speech checkpoint better. The fixed Spanish transcription screen compared the saved steps, found an earlier best checkpoint, and retained the distinction between word accuracy and how a voice sounds.
From the original notebook
Journey (do not ship final step)
- Female LoRA — initial Latam-ES female-only adapter.
- M+F base run — continued to step 10250 (
latam-es-mf). - Paso0 WER screen — best base checkpoint by WER was
checkpoint-step-008000(not the final 10250). - Polish — LoRA polish started from adapter at step 8000, run
latam-es-mf-polish, 1500 polish steps oncuda:0, checkpoints every 100 steps. - Polish WER (xAI STT, es) over the 5 fixed Spanish prompts:
- Best:
checkpoint-step-000400@ 6.1% WER (3/49 edits) - Final
checkpoint-step-001500@ 42.9% WER — worse; do not ship.
- Best:
- Release choice — promote polish-400 only; other polish checkpoints deleted on disk after selection.
Release artifacts here
| Path | What |
|---|---|
samples/sample_01.wav … sample_05.wav |
Spanish samples from polish-400 |
samples/prompts.txt |
Matching reference prompts |
docs/wer_report.md / wer_report.json |
Full WER table 100→1500 |
docs/polish-run-config.json |
Polish train config |
docs/latest.json |
Points at promoted step 400 |
Polish params (summary)
See docs/polish-run-config.json for full config. High level:
- Base adapter init:
WORKSTATION/checkpoint-step-008000 - Polish run root:
WORKSTATION/latam-es-mf-polish - Device:
cuda:0(power-capped card; intentional for this polish) - Steps: 1500; save every 100
- Promoted checkpoint on server:
WORKSTATION/checkpoint-step-000400
WER ranking (avg over 5 prompts)
| step | avg WER |
|---|---|
| 400 | 6.1% |
| 100 | 10.2% |
| 900 | 12.2% |
| 200 / 1100 | 14.3% |
| 1000 / 1200 | 16.3% |
| 700 | 18.4% |
| 800 | 24.5% |
| 300 / 600 | 26.5% |
| 1300 / 1400 | 28.6% |
| 500 / 1500 | 42.9% |
STT judge: local xAI audio shim → grok-transcribe, language es.
Explicit non-goals
- Do not ship polish-1500 / TRAIN_DONE final solely because training completed.
- Prefer polish-400 (or re-listen top-3: 400, 100, 900) for release.
Deployment (2026-09-11)
Polish-400 merged + NF4 on the mfwin RTX 3060 (WSL2), served via
OpenAI-compatible POST /v1/audio/speech, set as Hermes default TTS
(breeze_latam) on .51/.54/.55/mac with boot autostart. Full report:
docs/nf4-deploy.md. Winner 10-prompt wavs under
nf4/; reproducible deploy kit under deploy/.
Keep exploring
- README.md — latam-es-mf-polish-2026-09
- nf4-deploy.md — docs
- nf4-rehost-op54-lazy.md — docs
- wer report.md — docs
Original experiment record. Workstation paths have been generalized. Detailed measurements below retain their original workload and validation boundaries.